Use AI-based models to run text recognition and extract data from your scanned documents, archives, books, and push them to their full digital potential.
| Model | Capabilities | Usage |
|---|---|---|
| Calfa Gen One |
Armenian HTRArabic HTR
In-image location
A generic, cost-effective model for Arabic and Armenian |
Try the demo Available as an API |
| Calfa Gen Extended |
Armenian HTRArabic HTRLatin HTR
In-image locationFields/forms detectionStructured output
A generic model specially enhanced for multilingual documents and special output formats |
| Model | Capabilities | Usage |
|---|---|---|
| hye-calfa-n | OCR model for Armenian | Damaged, historical and noisy printed documents |
| calfa/hye-paddle | Open text-recognition models for Classical, Western and Eastern Armenian | |
| calfa/hye-tesseract | Open OCR model for Classical, Western and Eastern Armenian | Trained on a diverse range of documents: noisy texts, historical fonts, Armenian newspapers |
Custom models
We develop tailor-made models for any language or special script, trained on your own documents.
Contact us| Corpus | Script and documents | Volume | Recognition rate | Partners |
|---|---|---|---|---|
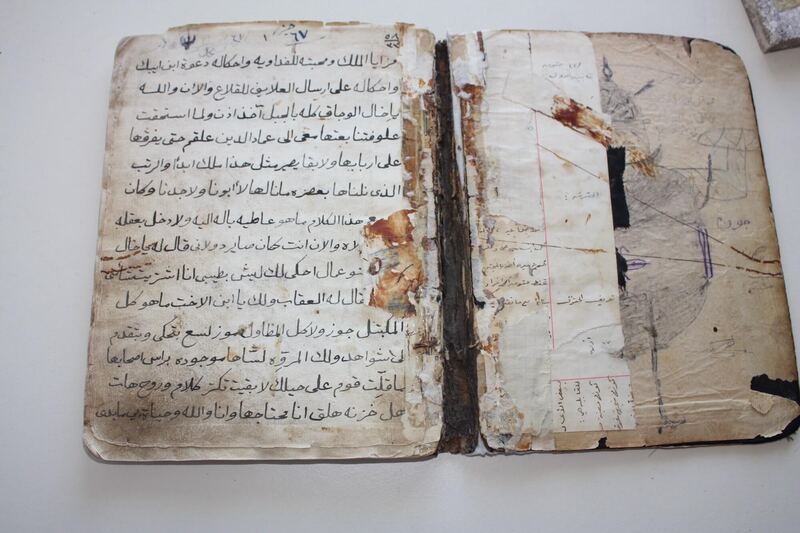
| The Sīra of Baybars2023–2024 | Middle Arabic · 20th-century manuscripts | 35,000 pp. | 98%average · 96 to 99% depending on the manuscript | ANR LiPoL · Ifpo |
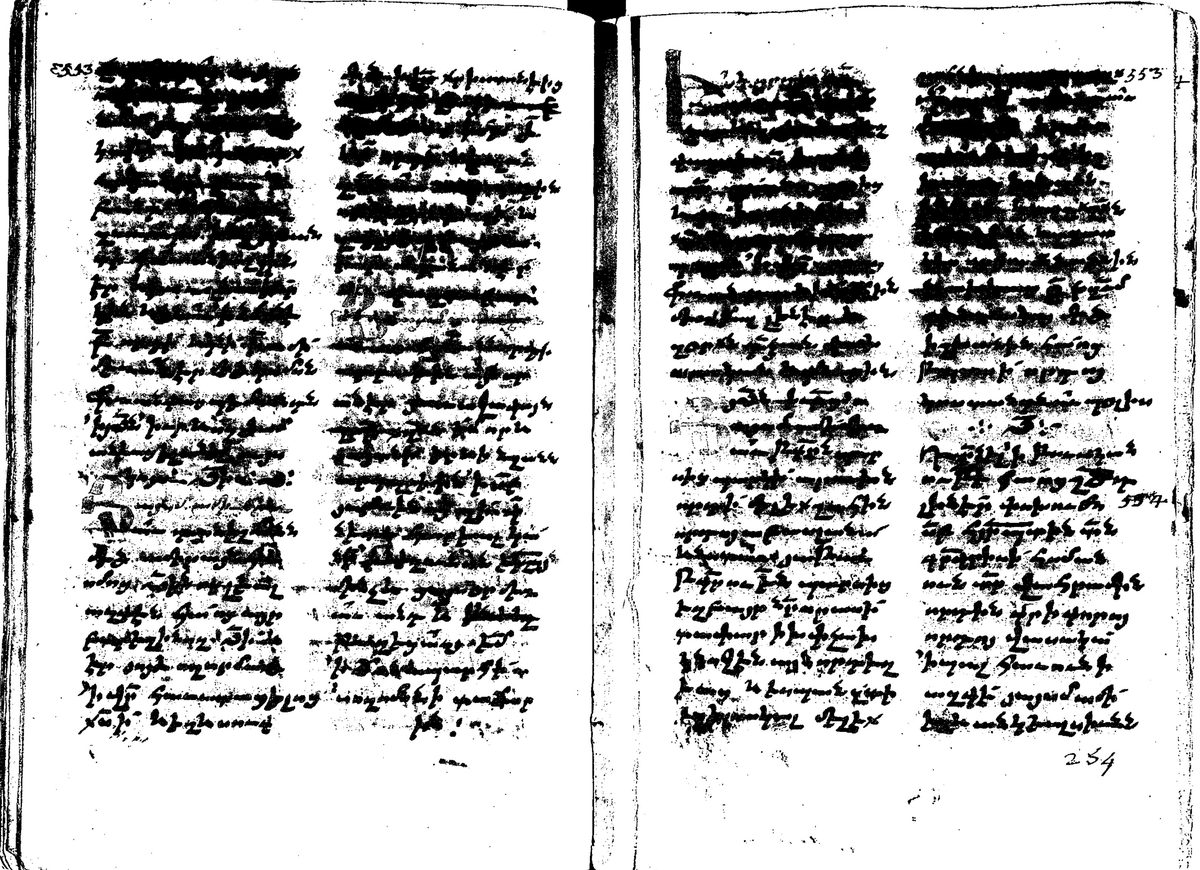
| Catalogue of the San Lazzaro manuscripts2022–2024 | Armenian · printed catalogue in 8 volumes, structured as a searchable databaseover 2,000 manuscripts described | 6,250 pp. 1.3M words | 99.2%of characters recognized, on old and degraded scans of the printed catalogue | Mekhitarist Fathers of Venice |
| TariMa | Arabic, Maghrebi scripts · manuscripts, lithographs, prints (17th–20th c.)available in BINA, the BULAC area studies digital library | 10,000 pp. | 97.2%on average | BULAC · CollEx-Persée · DISTAM · IREMAM |
| Islamic History Open Data Platform | Arabic · printed editions of 15th-century historians | — | 99.5%average · generic model | Ghent University, ERC project 2017–2021 |
| ChiKnowPo2024 | Chinese · imperial xylographic editionsmodel trained from few annotated pages | — | 96–99%reading order correct at 97.81% | University of Strasbourg · CollEx-Persée |
Character recognition rate: share of correctly recognized characters (100% − CER), specific to each corpus.
3,000 handwritten pages transcribed by AI
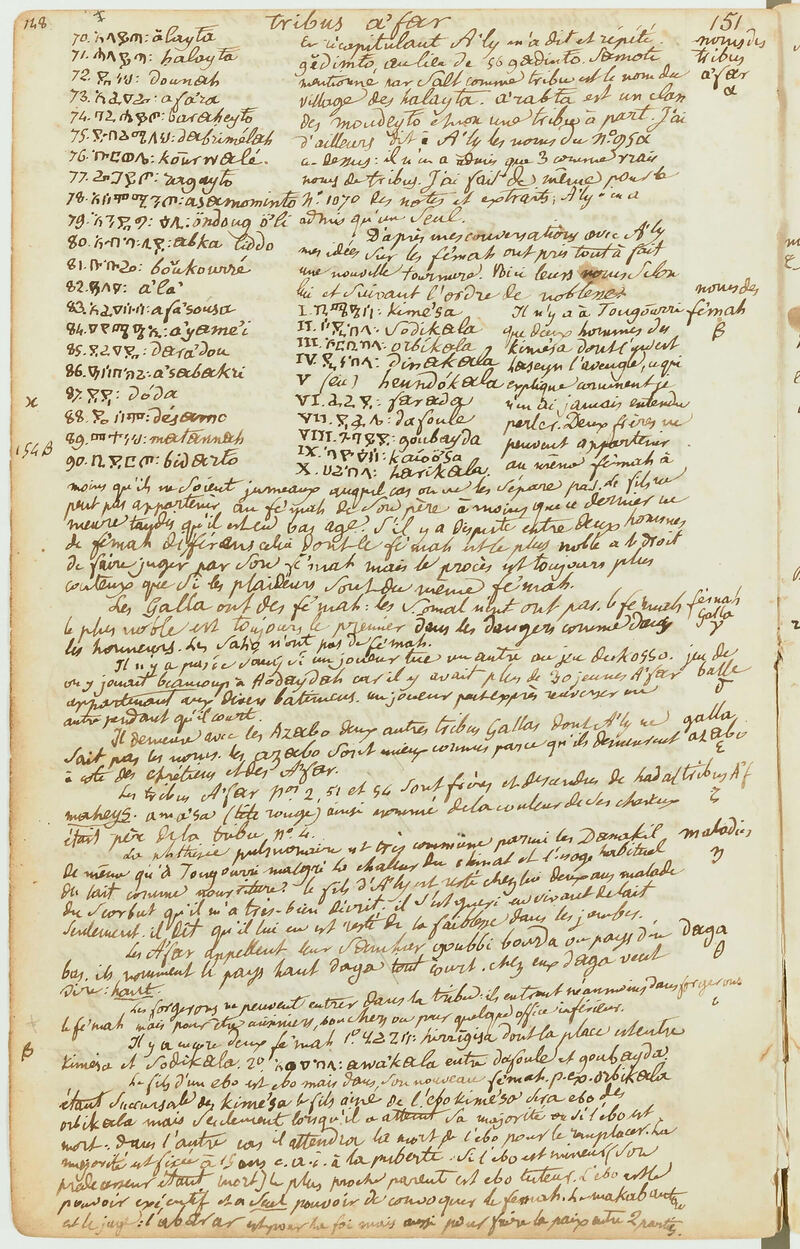
Notebooks from his journey in Ethiopia (1837–1848) mixing Ethiopic, Latin, Arabic, Hebrew and Greek scripts, transcribed by a triple HTR model, with the BnF and CNRS–IMAF.
98% recognition accuracy
A specialized HTR model transcribed all 35,000 Middle Arabic pages of the Sīra corpus gathered by the project, copied in the 20th century by several hands, from the most careful to the most cursive, on images of highly variable quality.
Recognition directly on microfilms of two 17th- and 18th-century BnF manuscripts, available on Gallica. Damaged documents finally readable.
Get 20 pages offered to test our text recognition in Arabic and Armenian on your documents
Try the demo now
To process printed or simple, handwritten documents in Arabic or Armenian script, our ready-to-use general AI models offer you and economical solution for an excellent performance. Try it now online.
For any corpora in non-Western language, dialect or from a complex hand : get an unmatched text recognition accuracy by using a custom AI model.